Sowing heterogeneity
Before a road is built there is only a landscape of infinite decisions. It takes teams of experts to map, image, and graph each possible route. Even when feasible routes are chosen, there are sensitive ecologies, costs, and property lines to navigate. Each route must be assessed on a variety of metrics before a final route is staked and the “real” work can finally begin.
In this way, road building can be seen as an example of the explore-exploit tradeoff: an enormous amount of work goes into “exploring” the best route among a wide set of possibilities before the road is laid down and “exploited” by motorists.
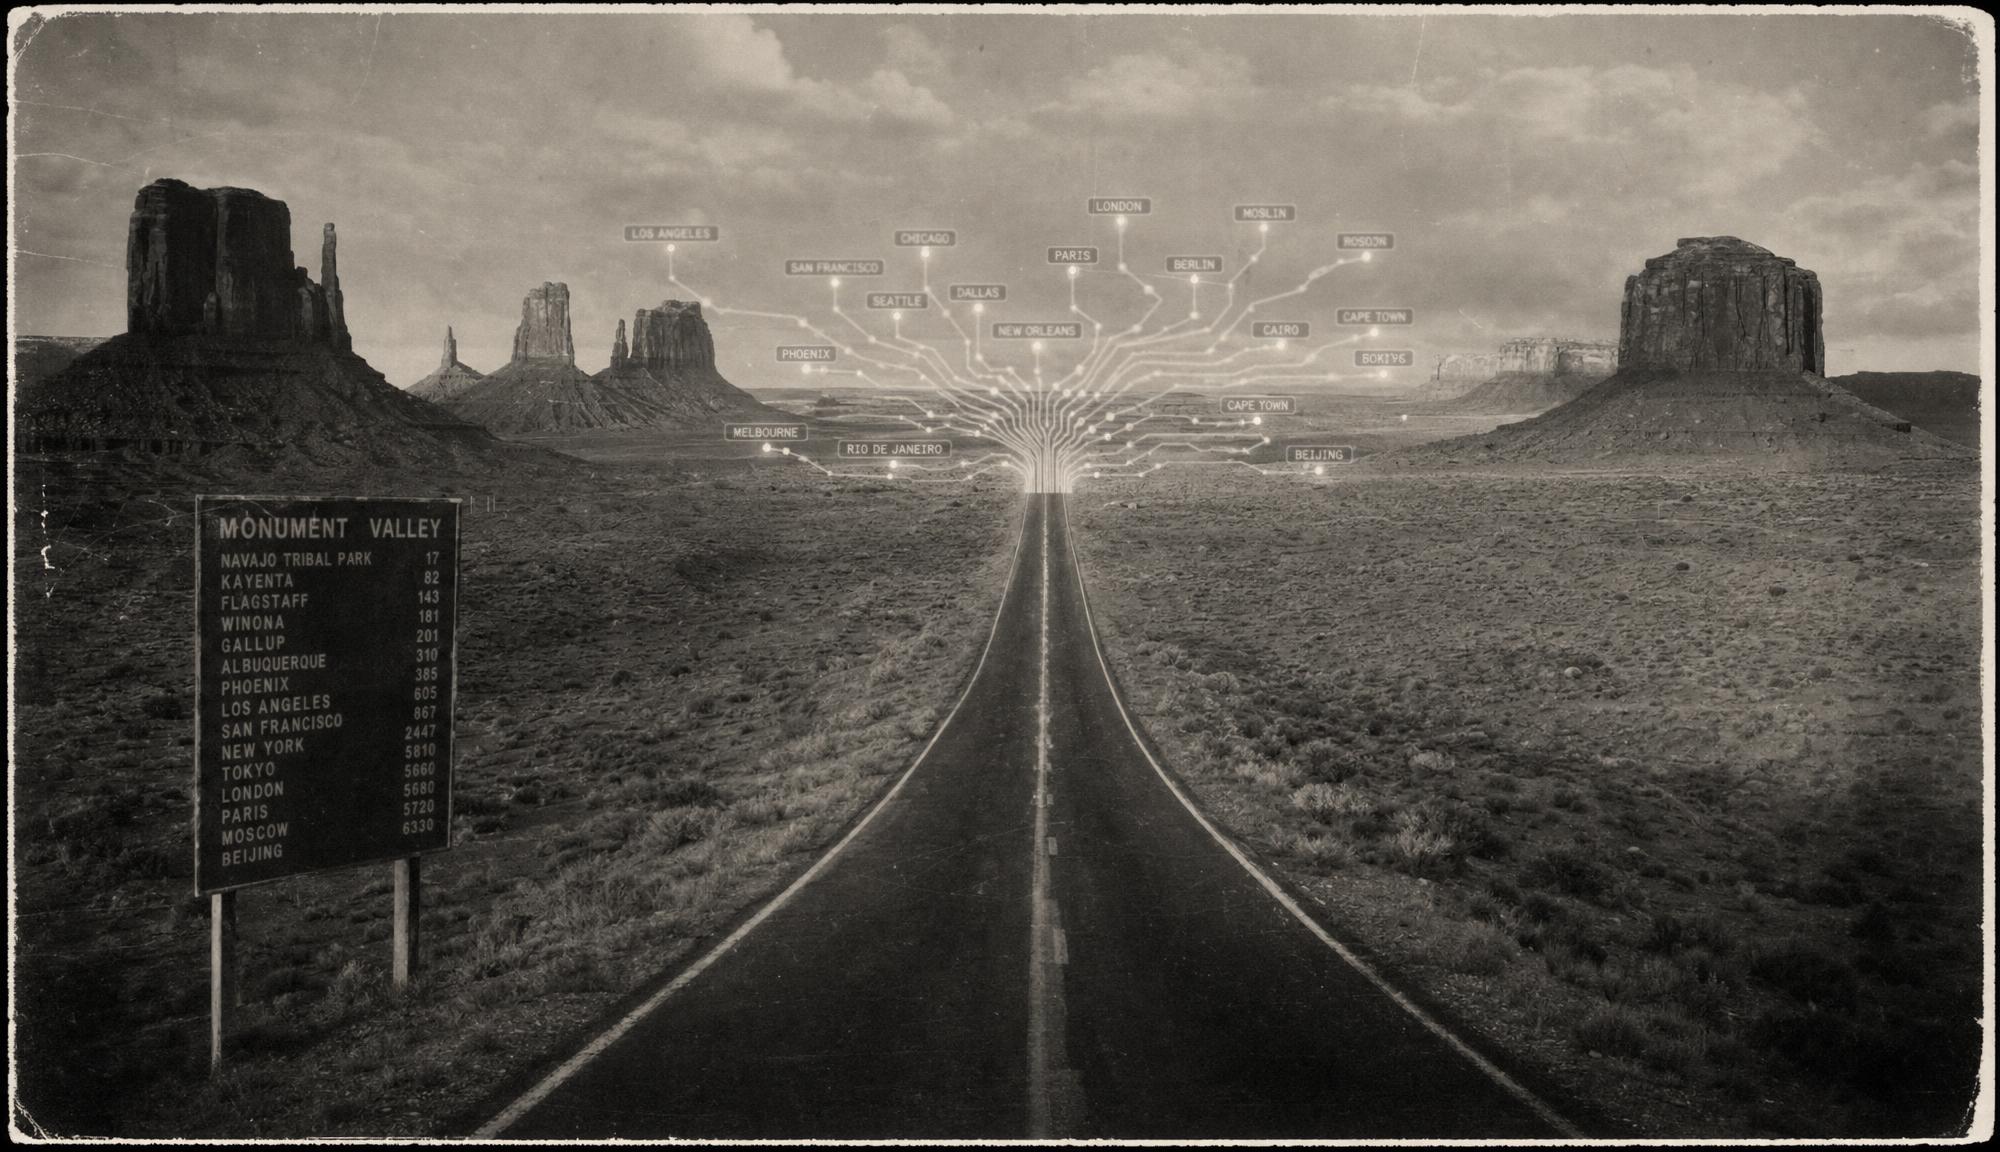
The same tradeoff exists for building any complex system. In user-centered design, exploration often takes the shape of needfinding, technological probes, and low- and high-fidelity prototyping. This extensive exploration work is necessary given the effort involved in producing and deploying systems that meet user needs, scale, and offer the flexibility necessary to adapt over time.
Furthermore, when these systems need to adapt to different deployment scenarios, designing and building their configuration mechanisms can be challenging.
AI coding agents upend these assumptions. Now, trying out a new variation is as straightforward as launching a new agentic process that can branch and rebuild a codebase, and this can be done in parallel with other tasks. This means that not only can we now test functional prototype/systems in real world contexts, we can potentially also deploy a larger variety (one might say, a requisite variety) of solutions. Our tooling can now approximate the heterogeneity of the field.
Increased maintenance is a potential pitfall. More on that later. For now, let us consider a few examples of how agentic coding has changed the way we think about developing research systems.
Research applications as patterns
Research applications are designed with exploration in mind. In HCAI, we use applications to probe the world to help us understand how different well-understood behavioral mechanisms play out in situ.
Storybook is one such application. Storybook uses generative AI to transform user stories into illustrated narratives with consistent character representation. People describe themselves and their situation in their own words, design a personalized avatar, and produce a visual story that advice givers then read and respond to. The system can be tuned for different deployments via a human-legible configuration file. Researchers can control dozens of aspects of the system, including how avatars are created, what AI models are used, how stories are structured, the types of responses that are allowed, etc. To create a new deployment, researchers modified an extensive configuration file and enabled a new route on an existing installation of Storybook, or cloned the code and launched their own installation from scratch. This configuration method was well established, but limited the tunable components to those that the developers had enabled.
Like so much that has changed since the fall of 2025, our approach to launching Storybook deployments completely shifted. Now, rather than a relatively stable code base with parameterized deployments, the codebase and deployment configuration files serve as ingredients to an agentic coding system. A researcher baking a new Storybook deployment mixes the old coding patterns with their new requirements as well as guidelines to incorporate the latest third-party models and techniques. The result is an outcome designed specifically for their use case.
Experience Sampling becomes a feature
Two EV charging research systems built by HCAI researchers can also help illustrate the impact of agentic coding.
ChargeMinder is a full research application for changing plug-in behavior among electrified vehicle owners. It gives drivers charging reminders, goals, streaks, feedback about their charging and driving behavior, and educational content. It also uses Smartcar, an API for connected vehicles, to observe driving and charging-related vehicle state. Because the intervention lives inside the app, researchers can control the surrounding experience: what the driver sees, when the prompt appears, what feedback follows, and how the behavior is represented over time.
Another project focused on vehicle-to-grid (V2G) participation. V2G systems depend on drivers making their cars available to the grid at useful times. In this project, researchers investigated whether people would choose to participate in V2G, and if so for how long and at what price.
The system used to run the V2G study leveraged Samply, an open-source experience-sampling platform with a researcher-facing server and a participant-facing mobile app. Samply let the team send prompts to participants in the field without building a full V2G application. Those prompts were combined with Smartcar, which exposed vehicle state and charging control, Qualtrics surveys, and backend services that linked participants, vehicles, prompts, and payments.
Rather than build a polished V2G app, the team in this case assembled a field system from other tools: Samply for experience-sampling, Smartcar for vehicle state and charging control, and Qualtrics for surveys. Backend services linked participants, vehicles, prompts, and payments.
These systems were two sides of a tradeoff between building a complete functional system versus using pre-existing tooling that required little building. ChargeMinder is a coherent system, but it requires the researchers to do everything that comes with building and deploying a bespoke app: design and development, QA testing, code reviews, configuring deployment infrastructures, etc. The V2G setup leveraged third-party tools and was therefore faster–most of the build and deployment concerns were already complete, but it had a less tailored participant experience. One treated the intervention as part of a product. The other treated the intervention as a field probe.
Agentic coding offers a way to reject this tradeoff by converting field assessment methodologies into a feature. Once bespoke research apps can be generated and revised quickly, ESM does not need to remain outside the system. Diary prompts, event-contingent questions, check-ins, follow-ups, and post-hoc surveys can be built directly into the deployment.
The ability to tailor applications to meet not only the needs of users but also researchers on a per deployment basis has the potential to revolutionize field research. Small research teams can now build systems specifically tailored to the study at hand: polished enough to make the intervention real, flexible enough to keep learning from the field.
One caveat is that agents are strongest where training data is plentiful, such as web frontends and Python services, versus where it is relatively sparse, such as iOS Swift. The agentic advantage is lower for projects with complex requirements, such as protecting participant data or running unattended for months. Generating a variant is cheap; verifying one is still human work.
Maintenance
The obvious cost of variance is maintenance. If every deployment becomes its own codebase, researchers inherit a family of systems rather than one system with many settings.
One answer is to rely on increasingly capable agents to handle maintenance work directly: updating dependencies, running migrations, and keeping related deployments in sync.
But another answer is that the road metaphor may not fit. A road is built for permanence. Many research systems are not. They may need to exist only long enough to answer a question, reveal a failure case, support a field study, or suggest a path to tech transfer. Others may branch into a family of related systems, each adapted to a different site, population, or intervention.
Agentic coding is a paradigm shift for knowledge work. Perhaps it is not surprising that it should also challenge our intuitions about research methodologies, systems, and contributions.
The title is a nod to an earlier HCAI paper.